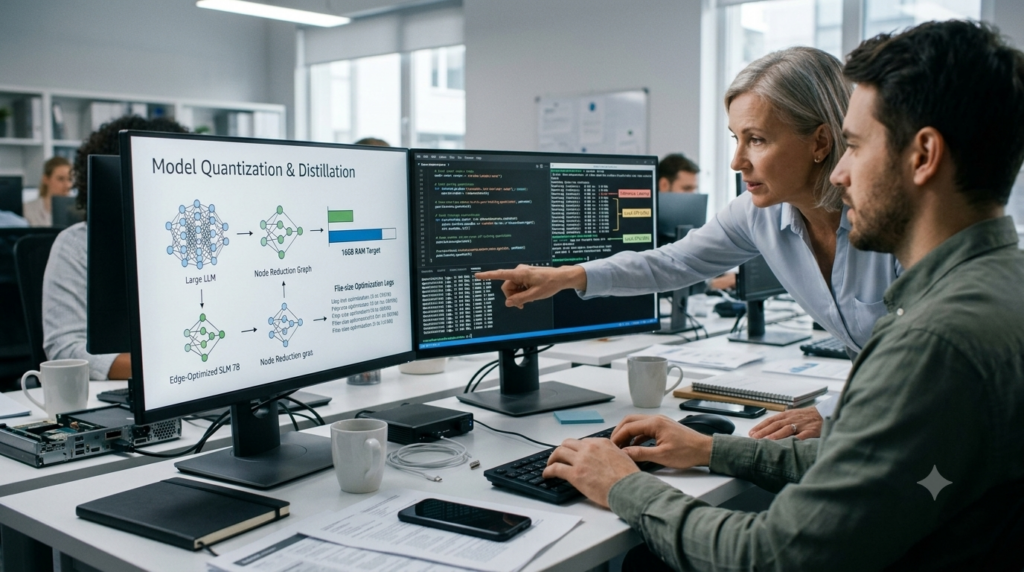
- Bigger is no longer automatically better. In enterprise technology, the obsession with massive parameters is giving way to speed, privacy, and capital efficiency. Small Language Models (SLMs) have emerged as the definitive enterprise architecture of choice.
While trillion-parameter frontier models excel at creative broad-domain synthesis, enterprises rarely need a model that can compose sonnets. They need models that parse insurance policies, extract structured tabular data, and validate code without multi-million-dollar cloud API overheads or data compliance headaches.
What Are Small Language Models (SLMs)?
A Small Language Model (SLM) is an artificial intelligence model generally ranging from 1 billion to 14 billion parameters, optimized using specialized domain distillation, high-density training data, and post-training quantization. Unlike general-purpose Large Language Models (LLMs), SLMs are engineered to execute specific task domains with equal or superior accuracy at a fraction of the computational load.
SLMs vs. LLMs: Enterprise Comparison
| Metric | Large Language Models (LLMs) | Small Language Models (SLMs) |
|---|---|---|
| Parameter Scale | 70B to 1T+ parameters | 1B to 14B parameters |
| Deployment Vector | Cloud-only data centers (multi-GPU clusters) | On-premise servers, edge appliances, mobile devices |
| Data Privacy & Governance | Third-party vendor API risk | Air-gapped, zero-leakage enterprise hosting |
| Inference Latency | High / dependent on network queuing | Near-zero real-time responsiveness |
| Operating Costs | High per-token compounding rates | Predictable, up to 70% cheaper compute overhead |
Why Enterprises Are Pivoting to SLMs
Enterprise AI deployments are moving away from speculative prototypes toward sustainable, balance-sheet-focused applications driven by four distinct pillars:
- Edge and On-Device Processing: SLMs run directly on laptops, IoT hardware, and local machinery without constant internet connectivity, removing server bottlenecks completely.
- Data Sovereignty and Compliance: Strict regulatory frameworks penalize transmitting private customer data to remote API endpoints. Local SLMs allow complete in-house data retention.
- Sub-Millisecond Latency: Applications like customer service voice synthesis and fraud prevention require immediate execution that massive cloud round-trips cannot deliver.
- Domain-Specific Precision: Fine-tuning an SLM on internal company documentation produces fewer hallucinations than prompting general-knowledge models.
Top Small Language Model Families Leading the Industry
Depending on your technical constraints, the leading model families providing production-grade performance include:
- Microsoft Phi Series: Trained on synthetic textbook-quality data, offering top-tier mathematical reasoning and programmatic logic in tiny footprint profiles.
- Google Gemma Series: Lightweight, open models built directly from Gemini research, tailored for effortless transfer learning and local developer workstations.
- Mistral & Qwen Lightweight Variants: Highly versatile multilingual and task-specific architectures capable of handling custom retrieval-augmented generation (RAG) pipelines.
How to Deploy SLMs in Your Tech Stack: A 4-Step Checklist
- Isolate High-Frequency Use Cases: Identify routine tasks (such as metadata classification, support summarization, or entity extraction) that drain your cloud token budgets.
- Apply Quantization: Reduce model weight precision (such as 4-bit or 8-bit formats like AWQ or GGUF) to run inference directly on commodity CPUs or single enterprise GPUs.
- Integrate a Hybrid Routing Architecture: Direct 80% of routine task volume to your local SLMs, reserving frontier cloud models solely for complex reasoning tasks.
- Establish Regression Benchmarks: Continuously monitor domain precision against human ground-truth data to prevent semantic drift.
Frequently Asked Questions (FAQ)
Can a Small Language Model replace an LLM entirely?
No. SLMs excel at bounded, domain-specific tasks and structured workflows. Open-ended creative synthesis and complex multi-domain reasoning still benefit from larger frontier systems.
What hardware is required to run an SLM locally?
Modern quantized SLMs (under 7B parameters) run smoothly on standard workstations with 16GB RAM or entry-level discrete consumer GPUs, requiring no specialized server farms.

admin
Technical contributor at Trigun.live exploring foundation models, automated workflows, and practical software systems.